Cheaper & Faster
Inference
By using frontier research on KV cache transfer between models, cut your inference costs and time by 20%. Prefill runs on a small model, and decode on a large one.
Backed by  Combinator
Faster first responses, smaller bills
Measured result100k-token context
Time to first token
Llama 3.1 8B → 70B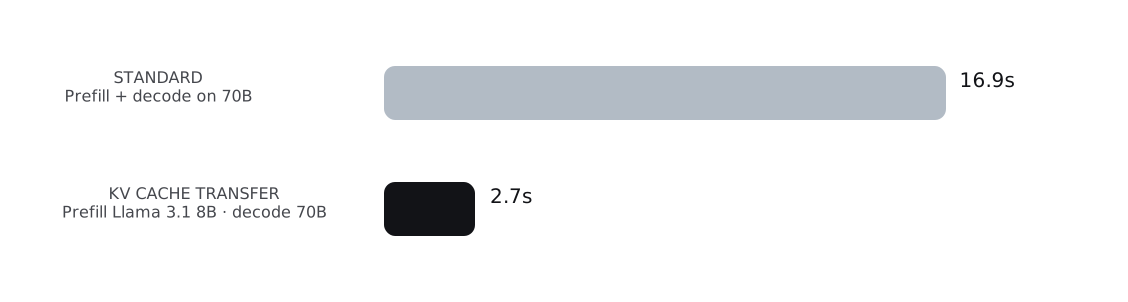
16.9s → 2.7s
$46.9k → $7.5k

Prefill cost scales with the size of the model doing the reading, which means today you pay large-model rates before the large model has produced a single word. On long inputs, that's most of the bill.
We prefill on a small model instead. Its per-layer K/V tensors are stripped of source rotary embeddings, projected head-wise into the target model's attention space, and re-embedded at target positions. The large model enters decode against a populated cache it never computed.
Prefill small and decode large. Transfers are gated on held-out quality and latency for every model pair. Ordinary prefill takes over whenever a pair doesn't clear, so the target model uses its usual inference path.
Our Research →Serviced open-weight models
Private, and we set it up. Independent benchmark leaderboards increasingly place leading open-weight models at frontier-level quality across common reasoning, coding, and knowledge tasks. We handle the GPUs and the serving. You change one line of config.
-
 Llama Meta
-
 Qwen Alibaba Cloud
-
 Mistral Mistral AI
-
 Gemma Google
-
 DeepSeek DeepSeek